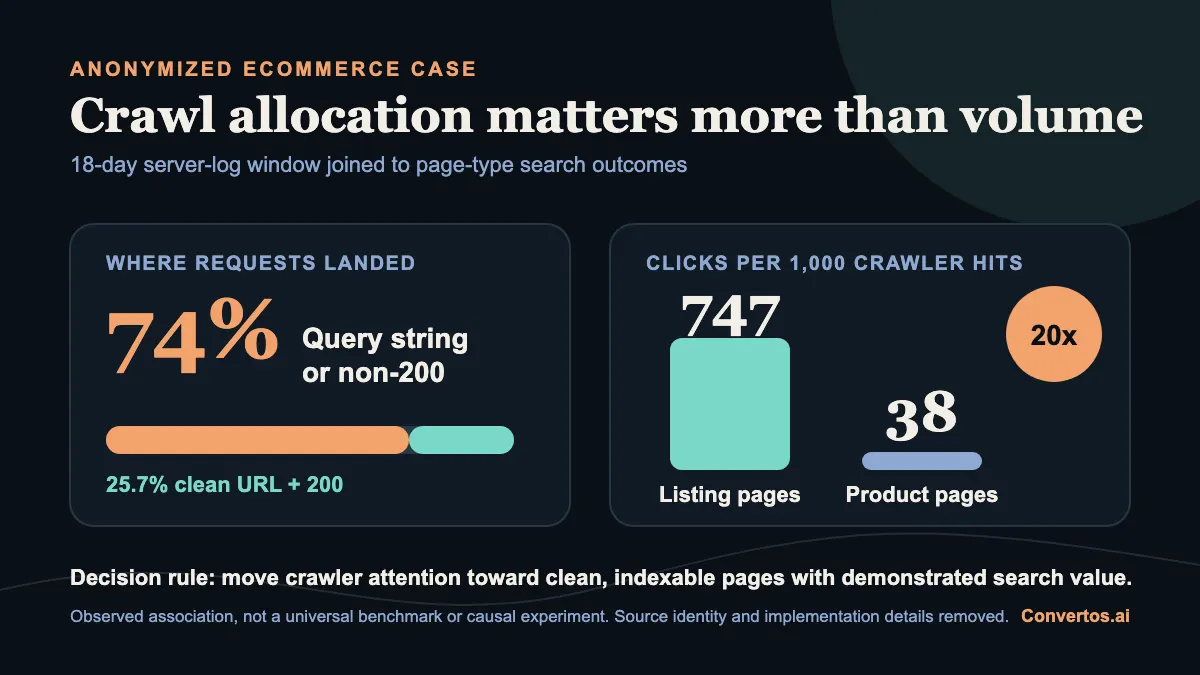
High crawler activity can hide weak discovery. In an anonymized 18-day marketplace log sample, 74% of verified search-crawler requests reached either a URL with a query string or a non-200 response. Only 25.7% reached a clean URL returning 200. The same review found that category and listing pages produced about 20 times more clicks per 1,000 crawler hits than product detail pages, yet daily crawler activity on those listing pages had fallen by 32%.
An anonymized ecommerce sample: request quality and crawl-to-click yield by page type.34-second visual summary: classify requests, compare page types, and retest the same cohort.Read the video transcript.
Key takeaways
Measure the share of requests reaching clean, canonical, indexable priority URLs. Total bot hits are not the success metric.
Segment by page type. In this observation window, listing pages returned about 747 clicks per 1,000 crawler hits versus about 38 for product pages.
Treat parameters and errors as separate causes even when they appear in one waste total. A parameter URL can return 200; a clean URL can still return an error.
Keep the denominator visible. Site crawls stopped at fixed volume ceilings, and server logs covered only part of the international host set.
Validate a release by where crawl moved, how quickly priority pages were fetched, and whether those pages later earned impressions and clicks.
Google describes crawl budget as the combination of crawl capacity and crawl demand. Its guidance is aimed mainly at very large or fast-changing sites; smaller sites whose important pages are crawled promptly should first investigate indexing, canonical, quality, and internal-linking problems (Google crawl-budget documentation, large-site guidance).
Observation from the anonymized sample
What it means
First decision
74% of requests reached parameterized URLs or non-200 responses
Most activity missed the clean-200 bucket
Split query-string and status-code waste before choosing a fix
67.8% of hits carried a query string
Tracking, feed, filter, sort, and campaign variants dominated discovery
Find which templates and links emit each parameter family
10.7% of hits returned non-200
Redirects and errors consumed a separate share of capacity
Break down 3xx, 4xx, 410, and 5xx by page type
Listing pages delivered about 20x the crawl-to-click yield of product pages
One page type was far more efficient in the observed window
Protect its internal links, sitemap presence, response time, and indexability
87.2% of compliant listing pages in the measured primary host were not fetched in the window
High-quality inventory remained unseen while low-value variants were repeatedly fetched
Reallocate discovery before asking for more crawling
These figures describe one large international marketplace during limited observation windows. They do not establish a universal benchmark or prove that changing one crawl rule will cause traffic growth. They do provide a useful diagnostic order: classify requests, quantify allocation, prioritize page types, change the generator, then retest the same cohort.
If you need to inventory canonical, indexability, and status-code defects before joining them to logs, start with the Convertos SEO audit workflow.
When crawl budget is a real ecommerce problem
Owner: technical SEO lead with engineering support. Check: compare Googlebot activity, index coverage, and server behavior for high-value templates versus low-value URL states. Metric: recrawl latency for new or updated PDPs/PLPs, plus the share of crawls spent on parameter and faceted URLs. Retest: after fixes, review server logs and Search Console over the next 2–4 weeks to confirm faster discovery and fewer wasted crawls.
Google defines crawl budget as the combination of crawl capacity limit and crawl demand for a site, and notes that most sites do not need to worry about it unless they are very large, change often, or show a high share of URLs as “Discovered - currently not indexed” in Search Console (Google crawl budget guidance). That matters for ecommerce crawl budget because large catalogs can generate near-infinite URL variants.
Term
Google-aligned meaning
What practitioners should check on ecommerce sites
Crawl capacity limit
Google limits crawling to avoid overloading the host; this is influenced by host health and responsiveness (Google crawl budget guidance)
Server response times, 5xx spikes, throttling, and whether important sections are slow or unstable
Crawl demand
Google crawls more when URLs are popular, frequently updated, or stale and need refresh
Whether new products, key categories, and seasonal pages are being recrawled quickly enough
Not a crawl budget issue
Google can crawl key pages promptly, but pages still fail due to quality, duplication, canonicals, or noindex
A practical decision rule: treat crawl budget as a real problem when all three are true:
The site is large or fast-changing enough to fit Google’s scope for crawl-budget work.
Important URLs are discovered or updated, but Googlebot spends substantial activity on low-value states such as sort, filter, session, or tracking parameters.
New or refreshed revenue pages are indexed late, even though they are internally linked and technically indexable.
Example: a large marketplace launches thousands of product variants and lets faceted navigation create URLs for color, size, price, sort order, and tracking parameters. Google has said parameterized URLs can be crawled if they are discoverable, so weak parameter governance can waste crawl activity on duplicate states instead of core PDPs and PLPs (Google Search Central discussion on query parameters). In that case, the problem is not “Google won’t index us” in general; it is that crawl demand is being pulled toward low-value URLs.
The caveat is important: if your store has a modest number of pages and new pages are crawled the same day, this is usually an ordinary indexing or quality issue, not a crawl-budget one. Start with evidence, not assumptions. If you need a structured review, run a focused technical audit before changing crawl controls.
Takeaway: on ecommerce sites, crawl budget is real when crawl capacity is constrained or crawl demand is misallocated, and the proof is delayed recrawling of important pages while bots spend time on URL variants you do not want prioritized.
The crawl-waste patterns that multiply URLs
The largest source of waste in the observed marketplace was not thin copy or slow discovery by itself. It was URL multiplication. Query-string variants accounted for 67.8% of verified crawler hits across the measured host set. Many were tracking, product-feed, campaign, sort, or filter variants that returned the same underlying content as a clean URL.
A useful distinction is between a low-value address and a low-value response. The first is created by URL rules: parameters, alternate paths, pagination, or duplicates. The second is created by what the server returns: redirects, 4xx, 410, or 5xx. The two can overlap, but they need different owners and fixes.
Waste pattern
Typical symptom
What logs should prove
Generator-level response
Tracking or feed parameters
The same product is fetched under many campaign addresses
High hit share, same clean target after stripping the query string
Stop emitting these variants in internal links and feeds; keep one canonical destination
Facets and sorts
One listing becomes many combinations
Repeated 200s on near-duplicate lists with little search demand
Keep only selected demand-backed landing pages discoverable; reduce crawlable combinations
Pagination
Deep pages absorb listing-page requests
Crawls and impressions spread across many paginated states
Preserve genuine discovery paths but avoid manufacturing infinite or duplicative sequences
Redirecting legacy paths
Bots repeatedly traverse old routes
High 3xx hit count and chains rather than single-hop redirects
Update internal links to final targets and collapse chains
Retired products
Old product URLs dominate 4xx or 410 traffic
Requests continue because internal or external references still exist
Keep truthful 404/410 responses, remove internal references, and offer a useful alternative only when one exists
Duplicate product layers
Two route families represent the same item
Shared product identity with self-canonical pages in both routes
Choose one preferred route and consolidate links, canonicals, and sitemaps
The anonymized review found that non-200 responses represented 10.7% of crawler hits in the latest window. Four-oh-four responses alone were 8.1% of all activity. Retired product paths dominated that error layer, while a live listing/search layer showed heavy churn. That difference matters: a 410 can be the correct response for a permanently retired product, but repeated crawling still tells you that something is advertising or remembering the URL.
Google's current documentation on faceted navigation recommends controlling the crawl space created by filters and parameter combinations. The safe implementation depends on whether a URL has standalone search value. Do not apply one blanket rule to every parameter. A useful filter landing page and a tracking variant may both contain ?, but they do not deserve the same treatment.
The practical takeaway is to build a URL-rule inventory before editing robots.txt. Name each generator, identify its business purpose, measure crawler hits and response outcomes, and decide whether the rule should remain discoverable, consolidate to a preferred URL, disappear from internal links, or return a truthful terminal status.
Use server logs to measure what bots actually fetch
Start with verified crawler requests and classify every hit by URL shape, response, page type, canonical state, and host. This prevents one headline number from hiding two problems. In the anonymized sample, 67.8% of hits carried a query string and 10.7% returned a non-200 response, but those categories overlapped. The combined waste share was 74%, not 78.5%.
Use a row-level table before building charts:
Separates duplicates from errors and capacity failures
Page type
product, listing, article, search, store
Allows crawl allocation to be compared with search value
Canonical state
self, other URL, missing
Shows whether the fetched address is preferred
Indexability
indexable, noindex, blocked, duplicate
Prevents a 200 response from being counted as useful by default
Host or market
measured host A, measured host B
Reveals instrumentation gaps and market-specific problems
Search outcome
impressions, clicks, no observed outcome
Enables crawl-to-search yield by page type
Then publish three ratios side by side:
Clean-200 share: requests to URLs without a query string that returned 200 divided by all verified crawler hits.
Useful-crawl share: requests to canonical, indexable, priority URLs divided by all verified crawler hits.
Crawl-to-click yield: Search Console clicks for a stable page cohort divided by crawler hits to that cohort, multiplied by 1,000.
The first ratio is easy to compute, but it is only a technical floor. A clean 200 URL may still be duplicated, canonicalized elsewhere, noindexed, or commercially unimportant. The second ratio requires joining logs to crawl data or a URL inventory. The third ratio brings business relevance into prioritization without pretending that a crawler hit directly caused a click.
Record the limits next to the result. In this case, both site crawls stopped at fixed URL ceilings and never reached depth five. Server logs covered only a subset of international hosts. Absolute URL counts were therefore minimums, and cross-host allocation could not be described as complete. A missing host in the log pipeline is a measurement gap, not evidence that crawlers ignored it.
This is why logs are more useful than a single Crawl Stats screenshot. They show the exact addresses requested and the responses returned. Search Console supplies the downstream impression and click layer. Joining the two lets you ask whether crawler activity is concentrated on the templates that can actually produce search demand.
Fix discovery and duplication without blocking valuable pages
Owner: technical SEO with engineering support. Check: align internal links, XML sitemaps, canonicals, robots rules, status codes, and parameter handling so only preferred ecommerce URLs are discoverable at scale. Metric: higher share of bot hits and sitemap URLs landing on canonical 200 pages, with fewer crawls to parameter, redirect, and duplicate states. Retest: compare logs, Search Console crawl/indexing patterns, and a fresh crawl 2–4 weeks after release.**
For large ecommerce sites, ecommerce crawl budget is usually wasted by mixed signals, not one bad setting. A category page may link to sorted and filtered URLs, the sitemap may list a different version, canonicals may point elsewhere, and robots.txt may block the very duplicates you need crawled to see the canonical. Google’s guidance is to improve crawl efficiency by reducing low-value URLs and keeping sitemaps current, not by blocking blindly with robots rules alone (Google crawl budget guidance).
A practical example: a storefront has /laptops, but templates also expose /laptops?sort=price-asc, /laptops?view=grid, and dozens of filter combinations. If merchandising wants only the core category indexed, then navigation, canonicals, and sitemaps must all reinforce /laptops as the preferred URL. If some filtered pages have search demand, treat them as intentional landing pages with self-canonicals, direct internal links, and sitemap inclusion. Everything else should be demoted from discovery.
Fix matrix
Signal area
Keep for valuable pages
Reduce for duplicate/low-value pages
Why it helps crawl efficiency
Internal links
Link directly to canonical PDPs, PLPs, and approved facet pages
Remove crawlable links to sort, view, session, and infinite filter states
Bots follow links first; link hygiene changes discovery fastest
XML sitemaps
Include only canonical, indexable 200 URLs updated recently
Exclude redirects, blocked URLs, non-canonicals, and thin parameter pages
Sitemaps should confirm priority, not list every reachable URL
Canonicals
Self-canonical on preferred URLs; point duplicates to the closest equivalent
Do not canonicalize unrelated pages or paginated sets to page 1 by default
Consolidates duplicate signals when pages must remain accessible
Robots controls
Allow crawling of pages that need canonical/index evaluation
Use robots.txt sparingly for clearly worthless patterns that should not be crawled
Blocking too early can hide canonical and noindex signals
Status codes
Return 200 for live canonicals, 301 for replaced URLs, 404/410 for removed items with no successor
Eliminate redirect chains and soft 404s
Bots waste requests on broken states and repeated hops
Parameters
Normalize tracking, sort, and display parameters; keep only approved indexable facets
Prevent endless combinations from being linked or surfaced in sitemaps
Parameter sprawl is a common crawl sink on ecommerce sites
Risk caveat: do not block or de-link pages that still drive revenue, long-tail demand, or internal site journeys. Test on one category cluster first. If “Discovered - currently not indexed” drops but key pages also lose crawls or impressions, you overcorrected. Use a controlled audit workflow before rollout: Convertos audit toolkit.
Practical takeaway: pick one URL pattern at a time, make every signal agree on the preferred version, then retest against logs and index coverage before expanding sitewide.
Prioritize page types with crawl-to-click yield
Page type should influence crawl priority. In the observed window, category and listing pages produced about 747 clicks per 1,000 crawler hits, compared with about 38 clicks per 1,000 hits for product detail pages. That is roughly a 20-fold difference. At the same time, daily crawler activity on listing pages had fallen 32%, even though total crawler volume across the measured hosts had risen 32%.
This does not mean every listing page deserves twenty times more crawling, or that product pages should be deprioritized as a class. The calculation is observational and page types serve different jobs. Product pages often cover long-tail demand and inventory detail; listings consolidate category demand and distribute internal links. The ratio is useful because it exposes a mismatch worth investigating.
Calculate the metric on stable cohorts:
crawl-to-click yield = Search Console clicks for the cohort / verified crawler hits to the cohort x 1,000
Page type
Clicks per 1,000 crawler hits in the sample
Other evidence
Priority question
Category/listing pages
About 747
High compliance, but most compliant URLs in the measured primary host were not fetched during the window
Are strong category hubs being starved while parameters and errors absorb requests?
Product detail pages
About 38
Compliance improved, but average internal links per product fell and response time increased
Which products earn demand, stay in stock, and deserve stronger linking?
Duplicate product layer
About 116 in the observed segment
Part of the layer shared product identity with another route family and showed redirect decay
Should this route be consolidated rather than promoted?
For listing pages, the same review found a sharp split between technical quality and crawler attention. About 94.8% of fetched listings met the review's compliance definition, yet roughly 87.2% of compliant listing pages in the measured primary host were not fetched during the log window. Response time was also slower than other major templates, and valid hreflang was present on fewer than 1% of listing pages in that host. High yield does not cancel those defects; it tells you the template is valuable enough to fix first.
For product pages, avoid spreading internal equity evenly across a huge tail. Average unique internal links per product fell 17% between crawl snapshots while the impression-earning tail grew. A useful prioritization cohort combines in-stock status, search demand, margin or strategic value, freshness, technical eligibility, and existing impressions. Strengthen links to the products that can benefit, rather than adding the same recommendation module to every URL.
The decision rule is simple: use crawl-to-click yield to find page types with a strong search return, then verify that the proposed pages are canonical, indexable, fast enough, internally linked, and present in clean sitemaps. The metric ranks investigation priority; it does not replace technical eligibility.
Verify that crawl moved, then check search outcomes
A successful release does not need to increase total crawler hits. It should move a larger share of requests toward clean, canonical, indexable priority pages without creating new discovery gaps. Verify that movement in logs first, then check indexing and search outcomes on the same page cohorts.
Gate
Metric
Baseline from the anonymized review
What improvement looks like
Allocation
Clean-200 share
25.7%
A sustained rise without hiding errors through missing logs
Parameters
Query-string hit share
67.8%
A decline in nonessential tracking, feed, sort, and filter variants
Errors
4xx share of crawler hits
8.1% in the latest partial-month window
Fewer requests to internally referenced dead URLs; truthful 404/410 responses remain
Listing coverage
Compliant listing pages fetched
12.8% in the measured primary host
Faster first fetch and higher coverage for selected priority listings
Efficiency
Listing-page clicks per 1,000 crawler hits
About 747
Stable or improving search yield as crawl reaches more priority listings
Product equity
Average unique internal links per product
Down 17% between crawl snapshots
Stronger linking for the selected demand-backed product cohort
Use a 7-day operational check and a 28-day outcome review. The early check catches broken routing, unexpected error growth, server strain, and whether parameters are still being emitted. The later review allows more time for recrawling, indexing, impressions, and clicks. Keep the comparison window, bot verification method, host coverage, and page cohorts consistent.
Release mapping is especially useful. The observed 4xx share rose to a 14.8% monthly peak and later fell to 8.1% in a partial-month window. That is a meaningful improvement signal, but the review could not attribute it to a specific change. Match the inflection to deployment records, then test whether the suspected fix actually changed the relevant URL rules and logs. Do not turn a timing coincidence into a causation claim.
Stop or roll back when one waste pattern falls but another expands. For example, blocking a parameter family can reduce visible crawler hits while leaving the same URLs in internal links, or it can hide the page from crawling before Google can see a canonical or noindex signal. Google notes that robots.txt controls crawling, not indexing by itself. Test on one parameter family or page cohort, inspect live responses and rendered links, then expand.
Store the before-and-after evidence in a repeatable SEO audit: exact date window, verified bot rule, included hosts, URL classifier version, page cohort, release ID, and the six metrics above. That makes the next decision evidence-based instead of turning crawl budget into a one-time cleanup project.
Disclosure
The case metrics come from a private technical review conducted in 2026 and are published here with permission in anonymized, aggregated form. Company, platform, domain, market, person, URL-pattern, and implementation identifiers have been removed; the original slides are not reproduced. The figures describe an 18-day log window and bounded site crawls that covered only part of the host set, so absolute counts are minimums. The relationships are observational, not a universal benchmark or a causal experiment.
FAQ
These questions reflect recurring People Also Ask, related searches, and practitioner discussions/forums reviewed for this update; the answers below rely on official documentation and the measurement framework above.
Does blocking parameter URLs in robots.txt save crawl budget?
Sometimes, but it can also prevent Google from seeing canonical or noindex signals. Remove unwanted parameter URLs from internal links and sitemaps first, then test one parameter family before expanding the block.
Do canonicals stop duplicate URLs from being crawled?
No. A canonical is a consolidation signal, not a crawl prohibition. Use it with clean internal links, sitemap discipline, and generator-level fixes.
What is a useful-crawl share?
It is the percentage of verified crawler requests that reach canonical, indexable, priority URLs. Track it beside clean-200 share so technically valid but low-value pages do not look like success.
How long should an ecommerce crawl-budget test run?
Use a 7-day operational check for routing, errors, latency, and continued parameter generation, then a 28-day outcome review for recrawling, indexing, impressions, and clicks. Keep the page cohort and measurement rules unchanged.